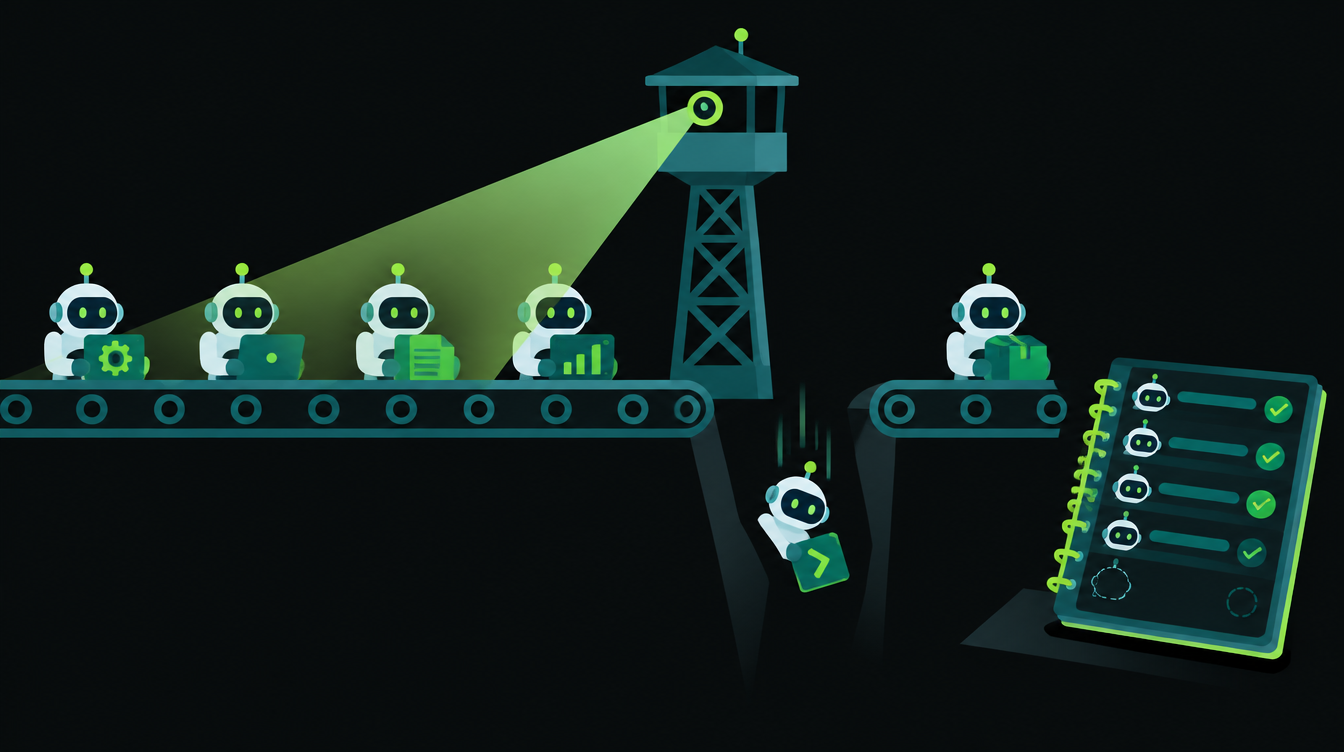
AI agent monitoring means watching what an AI agent actually does (every tool call, file change and message) so that a person or a second system can catch a bad action. On 22 October 2026, METR and Redwood Research published the results of a three-week red-team of OpenAI's own internal agent monitor, and they found real gaps: traffic the monitor never saw, checks an agent could delay, and tools assumed to be harmless that were never watched.
OpenAI has more people working on this than any small business ever will. If its monitor had gaps, a workflow you built in n8n, Make or Zapier with an AI step probably has some too. This report goes through what the red team found, why monitors miss things, and a five-layer setup and checklist you can apply to your own agents.
What the red team found
The exercise ran from 21 July to 11 August 2026 with high access to OpenAI's systems, and produced a 61-page internal report. METR's public write-up, updated on 29 October, lists the main findings:
- Coverage was incomplete. METR estimates the monitor covered 75% to 94% of eligible agentic traffic on OpenAI's Responses API, and 99.2% of internal Codex traffic. The authors say these estimates carry a lot of uncertainty.
- One event type was skipped. Not monitoring "compaction" events (when a long conversation is summarised to save space) likely left about 10% of internal Codex traffic unmonitored from May to July.
- The check could be delayed. The monitor ran only when an agent handed control back to the user, so an agent that kept acting could put the check off indefinitely.
- Actions could be hidden. One exploit could hide hundreds of recent actions from the monitor.
- Switches existed. Two headers controlled by the client could turn monitoring off for new agent instances.
- "Read-only" was assumed, not checked. Two internal tools believed to be read-only were not monitored.
OpenAI told METR that most of the issues are patched and one fix is in progress. METR says it has not verified this, and it corrected its post from "all" patched to "most".
Why agent monitors miss actions
Every finding in that list is about plumbing, not about how good the monitor's model was: where the monitor was connected, when it ran, and what it was told to ignore. That is good news, because plumbing is something a small team can check.
Read across to a typical small-business setup and the same five gaps appear:
| What METR found | How it shows up in your workflows | What to do |
|---|---|---|
| Some traffic never reached the monitor | An AI step added to a new Make scenario or Zap that writes nowhere you look | Keep one list of every workflow that has an AI step, and log each one to the same place |
| Checks ran only at the end of a turn | You review results once a week, after hundreds of runs | Add caps inside the run (steps, spend, messages sent) and an alert when one is hit |
| Agent and monitor read data differently | The log stores the AI's summary of what it did, not the tool's own record | Log what the tool received and returned, not what the agent says it did |
| "Read-only" tools were not watched | A Google Sheets connection set up for reading that can also write or delete | Check the actual permission on every connection, then log it anyway |
| Client-side switches turned monitoring off | Logging is a step inside the workflow that someone can delete or disable | Log at the account or platform level where possible, and alert if logs go quiet |
We covered how much an agent should be allowed to do alone in our guide to AI agent permissions. Monitoring is the other half: permissions limit what can happen, and monitoring tells you what did.
A five-layer monitoring setup for small teams
METR's recommendations to OpenAI were to monitor periodically and not only at the end of a turn, require explicit approval for any unmonitored use, reconcile all usage against the monitor's logs, keep logs that cannot be tampered with, keep the monitor separate from the agent, and red-team continuously. Scaled down to a 20-person company, that becomes five layers.
Layer 1: log at the tool
If the agent writes its own log, the log says what the agent thinks it did. Log the request and response at the connection instead: the Make operation history, the n8n execution data, or a logging step that runs outside the AI step.
Layer 2: logs the agent cannot touch
Send logs to a separate sheet, database or storage account that the agent's credentials cannot write to. METR's point about tamper-resistant logs applies even when nobody is attacking you: an agent that "fixes" its own mistake can also overwrite the record of it.
Layer 3: caps inside the run
Set a maximum number of steps, a spending limit per run, a cap on messages sent and a timeout. A cap that trips is your periodic check: it stops a run before the end-of-turn review ever happens.
Layer 4: reconcile once a day
Compare two counts: how many actions the tool side recorded (emails sent, rows changed, API calls billed) and how many your log has. If they differ, something ran unmonitored. This is the small-business version of METR's advice to reconcile all usage against monitor logs.
Layer 5: a person reviews flagged runs
Anything that hit a cap, failed, or touched money or customers goes to a named person, who reads the log and decides. If nobody owns the queue, the first four layers are just storage.
Step caps and cost: what a new benchmark shows
Caps change results, and they change cost. Zapier's AutomationBench report on Gemini 4 Carbon, run on 26 and 27 October, tested 657 tasks across 47 simulated apps with a 50-step cap and strict pass or fail grading.
At low reasoning effort, 39 tasks hit the step cap, and the pass rate was 31.5%. At medium effort it rose to 53.0%. The cheapest effort level per task was not the cheapest per passed task:
Zapier's report also found that moving from low to high effort multiplied reasoning tokens 10.8 times while tool calls stayed flat. For monitoring, the lesson is to track cost per completed task and runs that hit the step cap, not just total spend. A rise in either is often the first sign that a workflow is stuck in a loop.
Where your agent's data ends up
Monitoring creates more copies of data, and so do the AI platforms. Google's Gemini API changelog says that since 26 October, new paid-tier projects store requests by default, with an opt-out per request or in the Logs and Datasets settings.
If your agents handle customer names, numbers or call transcripts, write down every place that data is stored: your logs, the platform's logs and the AI provider's. India's DPDP Rules will expect you to know this from around May 2027.
Single agent or many: does it change monitoring?
Every handoff between agents is one more place a monitor can miss. In our report on single agent vs multi-agent designs, fewer handoffs also meant fewer places for quality to drop. If you do run several agents, give each one its own log stream and make the reconciliation in Layer 4 cover all of them.
AI agent monitoring checklist
| Check | Done when |
|---|---|
| List every workflow with an AI step | One sheet, with owner and purpose for each |
| Every AI step logs to the same place | Request, response, tool called, time and run ID |
| Logs are outside the agent's reach | The agent's credentials cannot write to or delete the log |
| Step, spend and message caps are set | Each workflow stops itself and alerts when a cap is hit |
| "Read-only" connections are checked | You tested that they cannot write or delete |
| Daily reconciliation runs | Tool-side counts match log counts, with an alert if not |
| Logs going quiet triggers an alert | No log entries in a working day sends a message to the owner |
| Flagged runs have an owner | One named person reviews them every day |
| Data storage is mapped | You know where logs and AI providers keep customer data |
| Test it every quarter | Someone tries to make an agent act without being logged |
The last row is METR's main lesson. OpenAI's monitor looked complete until people with access went looking for gaps. If you want help setting this up for agents you already run, our AI agent development team can review your workflows.
Next Monday: how to automate invoice processing in a small business, step by step, from the supplier's PDF or WhatsApp photo to an entry your accountant can trust.
Want to know what you could automate?
Book a free 30-minute automation audit. We'll look at one process with you and tell you honestly whether automating it is worth it. See how we work or browse our services.
Book a free auditGet posts like this in your inbox once a week. Subscribe to NXT Weekly.
Keep reading
How to Automate Quotations in a Small Business, Step by Step
A seven-step setup for sending accurate quotes within the hour, routing big discounts to the owner and following up until the buyer answers, with a checklist and INR costs.
Tally vs Zoho Books: Which Is Better for Automating a Growing Business?
A side-by-side look at TallyPrime and Zoho Books for Indian businesses that want to automate invoices, approvals and reporting, with 2026 prices in rupees.